Novita AI publishes per-token pricing for 200-plus models; Hyperbolic publishes per-GPU-hour rental pricing instead. As of 2026-08-26, Novita AI lists Llama 3.1 8B Instruct at $0.02 per million input tokens; Hyperbolic lists H100 SXM at $3.19 per hour.
The two units do not convert, so no single winner is named. Match the axis to the workload.
Table 1. Novita AI and Hyperbolic compared on pricing structure, model catalog, GPU hardware and company stage, retrieved 2026-08-26.
Dimension | Novita AI | Hyperbolic |
|---|---|---|
Primary pricing unit | Per million tokens, published per model | Per GPU per hour, published per GPU type |
Sample published rate (2026-08-26) | Llama 3.1 8B Instruct: $0.02 input / $0.05 output per 1M tokens | H100 SXM: $3.19 per hour† |
Largest published context window | 1,000,000 tokens (DeepSeek-V4-Pro-0813, GLM 5.2, Kimi K3) | Not published on Hyperbolic's own pricing pages as of retrieval |
Model catalog | 200+ models: LLM, image, video, audio, embeddings | Chat completion models listed through the Hugging Face router; custom models via on-demand GPU |
GPU hardware for rent | H100, H200 (bare metal, billed per second) | H100 SXM, H200, B200 (hourly, refreshed weekly) |
Cryptocurrency payment | Not documented | Documented in vendor blog |
Headquarters | San Francisco, California | San Francisco, California |
Funding stage | Bootstrapped, no external round reported | $20M total through a Series A closed December 10, 2024 |
Table note: † GPU rental rate, not a per-token model rate. The two figures use different denominators and are not ranked against each other; the table separates them by row instead.
Llama 3.1 8B Instruct costs $0.02 per million input tokens and $0.05 per million output tokens on Novita AI, against $3.19 per hour for one H100 SXM GPU on Hyperbolic, two units that cannot be netted into a single price without assuming a request volume.
DeepSeek-V4-Pro-0813 carries a 1,000,000-token context window on Novita AI's price list, the largest published figure in this comparison.
Hyperbolic's own pricing pages, retrieved 2026-08-26, do not publish a comparable per-token or context-window figure for chat completion.
Basis and method
Every figure in this article is Basis 2: aggregated from published vendor documentation, not produced by testing. We collected Novita AI's model prices and context windows from its own pricing page, and Hyperbolic's GPU rental prices from its own marketplace page, both retrieved 2026-08-26.
We collected Hyperbolic's serverless model listing from Hugging Face's own Hyperbolic provider page, retrieved the same date, because Hyperbolic's documentation does not publish a comparable per-token price table as of that date.
We did not run a model, a benchmark, or a load test for this article. Full sourcing is documented on the comparison methodology page.
Decision axes: this comparison orders Novita AI and Hyperbolic by published pricing structure first, model catalog breadth second, and GPU hardware access third, since these are the only dimensions both companies document publicly as of the retrieval date.
Novita AI publishes a 200-model price list with per-second GPU billing
Novita AI is a San Francisco cloud platform selling API access to open-weight language, image, video and audio models alongside on-demand GPU instances, according to its own homepage, retrieved 2026-08-26.
The same homepage states 200-millisecond latency and 99.5% uptime for its model APIs; both figures are Novita AI's own marketing statements, not independently verified by LLM Waves Research.
Novita AI and Hyperbolic joined Hugging Face's Inference Providers program on the same date, February 18, 2025, according to Hugging Face's own announcement.
Per-model rates across the catalog
Novita AI's pricing page lists DeepSeek-V4-Pro-0813 at $1.32 input and $3.96 output per million tokens with a 1,000,000-token context window, Llama 3.1 8B Instruct at $0.02 and $0.05 with a 16,000-token window, and Kimi K3 at $3 input and $15 output with a 1,000,000-token window, all retrieved 2026-08-26.
Batch inference carries a 50% discount on input and output tokens for supported models, per the same page.
Image and video generation are priced per output unit rather than per token: Flux.1 Kontext Dev costs $0.0225 per image, Flux.1 Kontext Pro costs $0.36 per image, and Kling v3.0 Pro costs $0.112 per second without audio or $0.168 per second with audio, retrieved 2026-08-26.
Novita AI's documentation, retrieved on the same date, states OpenAI-compatible request formatting. An existing OpenAI client can point at Novita AI by changing only the base URL and model string.
The per-token rate does not move in a straight line as context window and parameter count grow across Novita AI's catalog.
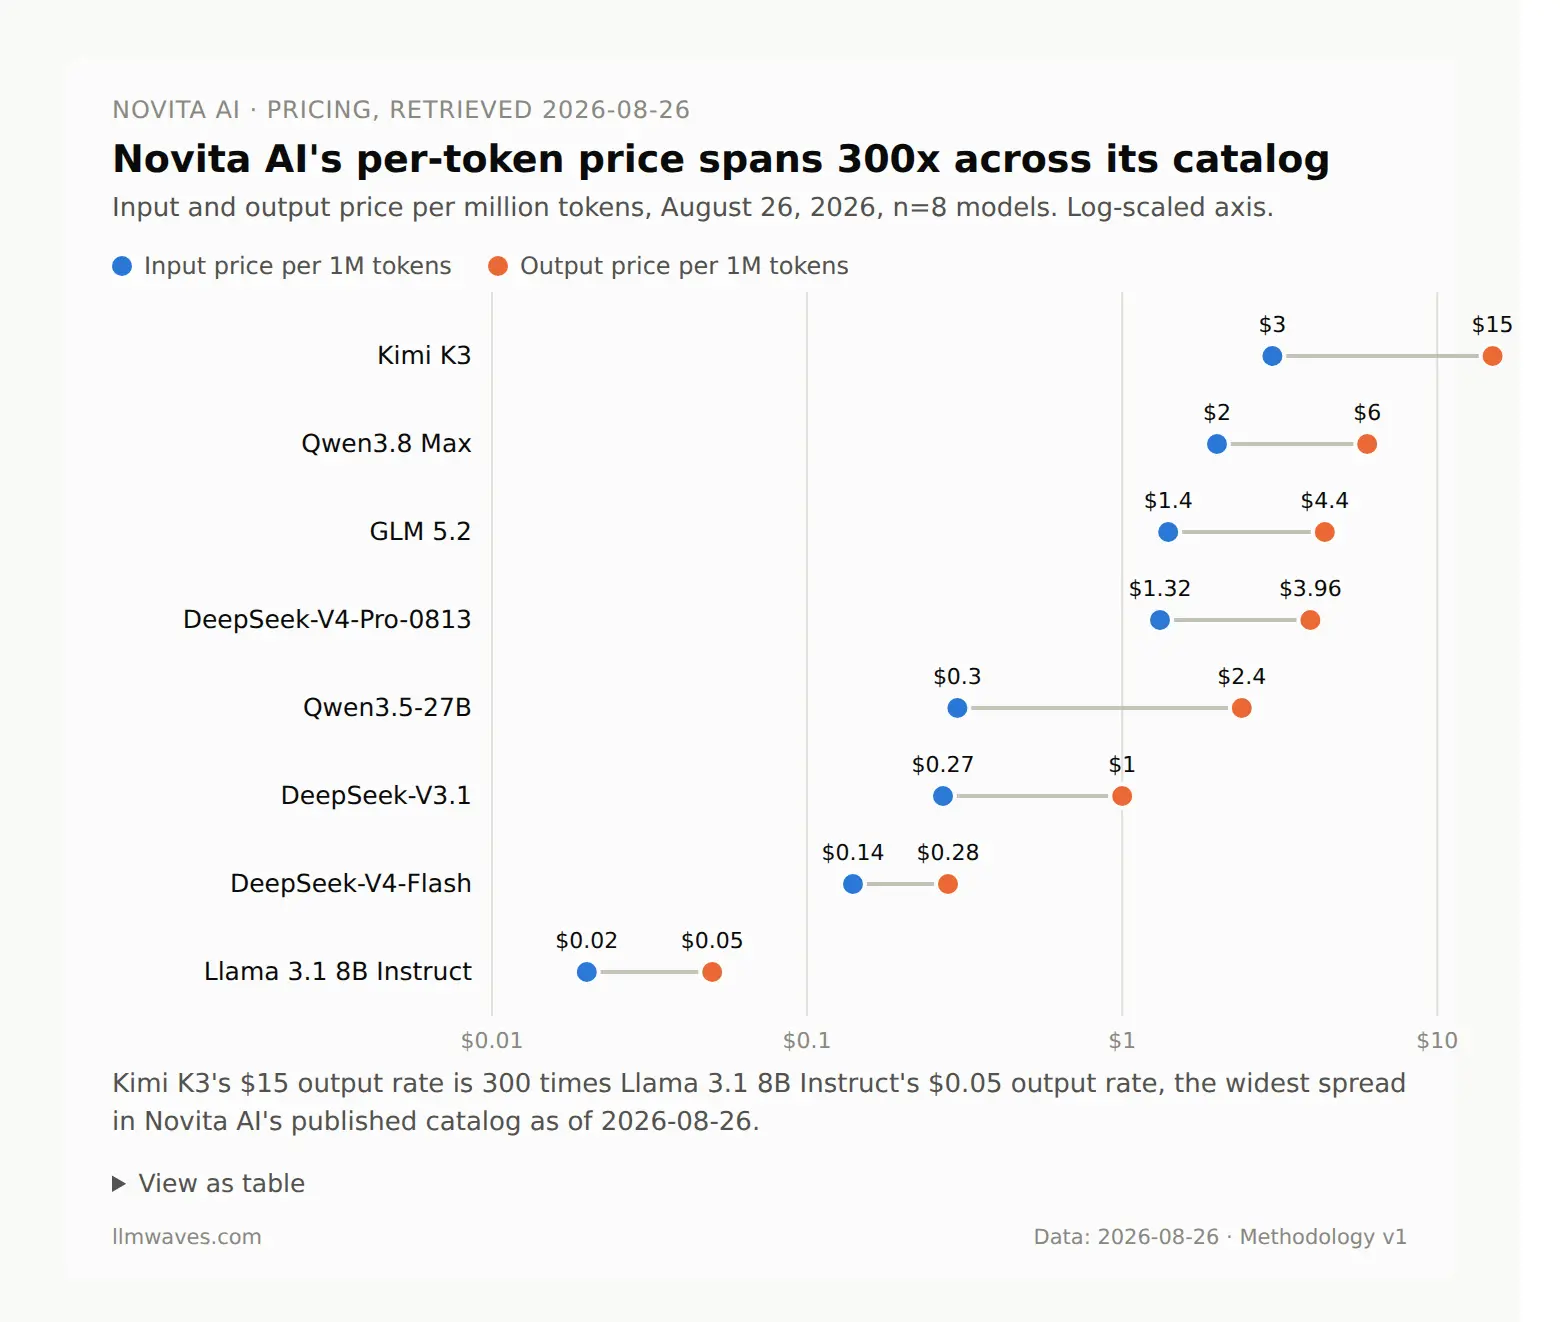
Kimi K3's $15 output rate is 300 times Llama 3.1 8B Instruct's $0.05 output rate, the widest spread in Novita AI's published catalog as of 2026-08-26.
The Novita Coding Plan
Novita AI sells a subscription product outside its per-token catalog. The Novita Coding Plan bundles nine models, including GLM-5, Kimi K2.5 and DeepSeek V3.2, into flat monthly tiers billed independently of per-token usage, according to Novita AI's own coding-plan page, retrieved 2026-08-26.
The page states monthly billing with cancellation at any time; its dollar figures did not render in static form, so this article does not state a specific tier price.
No comparable flat-rate coding subscription is documented on Hyperbolic's site.
Hyperbolic prices GPU hours and keeps model inference behind the Hugging Face router
Hyperbolic is a San Francisco GPU cloud and AI compute marketplace, co-founded by Dr. Jasper Zhang and Dr. Yuchen Jin, according to Hyperbolic's own funding announcement, dated December 10, 2024.
That announcement reported $20 million in total funding across a $725,000 pre-seed round, a $7 million seed round, and a $12 million Series A led by Variant and Polychain Capital, plus 40,000 developers and more than 1 billion tokens processed daily as of that date.
Hyperbolic's homepage, retrieved 2026-08-26, states a newer figure of 250,000-plus builders.
On-demand GPU rental rates
Hyperbolic's marketplace page lists three on-demand GPU types with weekly-refreshed rates, retrieved 2026-08-26: H100 SXM at $3.19 per hour, H200 at $3.99 per hour, and B200 at $5.99 per hour, with no minimum commitment on the on-demand tier.
Reserved and private-cloud tiers trade a discount for a term commitment starting at one week, per the same page.
Hyperbolic's three published on-demand rates scale with memory bandwidth rather than price alone.
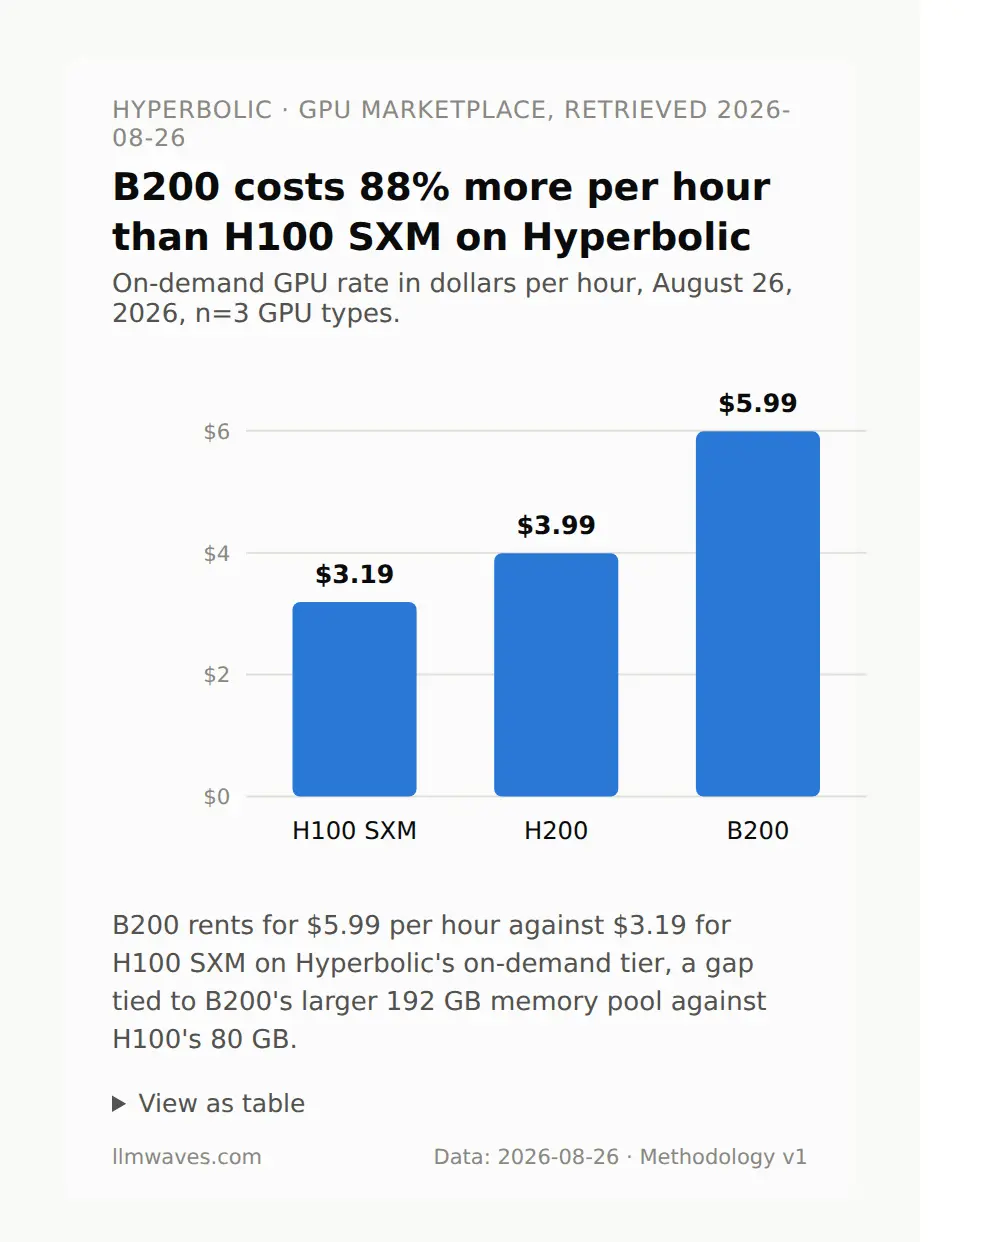
B200 rents for $5.99 per hour against $3.19 for H100 SXM on Hyperbolic's on-demand tier, a gap tied to B200's larger 192 GB memory pool against H100's 80 GB.
Serverless models and cryptocurrency payment
Hyperbolic's own pricing and documentation pages, retrieved 2026-08-26, do not publish a per-model, per-token price table for chat completion the way Novita AI's pricing page does; the current site structure organizes around on-demand, reserved, and private-cloud GPU rental rather than serverless per-token billing.
Hugging Face's own Hyperbolic provider page lists Llama-3.3-70B-Instruct as an available chat-completion model routed through Hugging Face's infrastructure and states that Hyperbolic's inference is "3 to 10x cheaper than competitors," a Hyperbolic-sourced marketing statement reported by Hugging Face rather than a figure independently verified by LLM Waves Research.
Hyperbolic documents cryptocurrency payment for GPU rental and inference in its own blog, retrieved 2026-08-26, a feature not documented on Novita AI's site (see "Does Hyperbolic accept cryptocurrency payment" below).
Novita AI and Hyperbolic share a headquarters city and little else about company stage
Both companies list San Francisco, California as their headquarters: Novita AI according to BuiltIn San Francisco's company profile, retrieved 2026-08-26, and Hyperbolic according to its own funding announcement.
Novita AI reports 11 employees and no external funding round, operating as a bootstrapped company per that same profile.
Hyperbolic reports $20 million in total funding through a Series A closed December 10, 2024, backed by Variant, Polychain Capital and a group of funds including Lightspeed Faction and GSR.
A one-week minimum on Hyperbolic's reserved GPU tier and Novita AI's cancel-anytime coding subscription both point toward short-commitment pricing rather than long contracts.
What we did not measure
We did not independently measure latency, throughput, output quality, or uptime for either provider in this comparison; every number above is collected from vendor documentation, not produced by testing.
Quantization fidelity, long-context degradation past the published window, rate-limit behavior under concurrent load, and regional data-center latency are not covered for either company, since neither publishes that data on the pages retrieved for this article.
Use-case verdicts
Situational: Novita AI, for developers who want a flat monthly fee instead of metered billing. Its Coding Plan is the only documented flat-rate subscription between the two providers.
A team without a fixed monthly workload gets no benefit from this axis over per-token billing.
Situational: Novita AI, for teams pricing many open-weight models against one published list. Its pricing page covers 200-plus models against no equivalent public list from Hyperbolic.
A team already committed to a Hugging Face-routed workflow may not need a separate price list at all.
Situational: Hyperbolic, for teams renting raw GPU hours for training or fine-tuning. Its marketplace publishes H100, H200 and B200 hourly rates with no minimum commitment on demand.
Novita AI's bare-metal GPU pricing was not part of the pages retrieved for this comparison, so this is not a statement that Novita AI lacks the option.
Insufficient data: a direct token-for-token price ranking between the two companies.
Hyperbolic does not publish a comparable per-token rate on its own site as of 2026-08-26, so a single cheaper-provider verdict on inference pricing is not supported from these sources.
Is Novita AI or Hyperbolic based outside the United States
Neither is. Novita AI lists San Francisco, California as its headquarters according to BuiltIn San Francisco. Hyperbolic lists San Francisco, California according to its own funding announcement.
Both are United States companies by their own published addresses, retrieved 2026-08-26.
Does Hyperbolic accept cryptocurrency payment
Yes. Hyperbolic documents cryptocurrency payment for GPU rental and inference in its own blog, retrieved 2026-08-26.
Novita AI's pricing and documentation pages, retrieved the same date, do not mention a cryptocurrency payment option.
What is the Novita Coding Plan
The Novita Coding Plan is a flat monthly subscription covering nine models, including GLM-5, Kimi K2.5 and DeepSeek V3.2, according to Novita AI's own coding-plan page, retrieved 2026-08-26. Billing is monthly with cancellation at any time.
The page's dollar-figure tiers did not render in static form at the time of retrieval, so this article does not state a specific tier price.
Is Novita AI's API compatible with the OpenAI client format
Yes. Novita AI's documentation, retrieved 2026-08-26, states OpenAI-compatible request formatting for its endpoints. Hyperbolic's chat-completion models are documented as OpenAI-compatible when routed through Hugging Face's infrastructure, per Hugging Face's own Hyperbolic provider page, retrieved 2026-08-26.
Which provider publishes a larger context window
Novita AI publishes the larger figure among the sources retrieved for this article: 1,000,000 tokens on DeepSeek-V4-Pro-0813, GLM 5.2 and Kimi K3, against no context-window figure published on Hyperbolic's own pricing pages as of 2026-08-26.
Hugging Face's Hyperbolic provider listing names Llama-3.3-70B-Instruct without stating its context window in that listing.
Both price lists move without a changelog
Both vendors' pricing pages mutate without a public changelog, so a dollar figure or context-window number above reflects its retrieval date, not a live price. A reader pricing a production workload should confirm the current rate on the provider's own page. Two more pairs sit one click away from this one: the full sourcing and provider profile behind this article.